-
About 5% of the data contained deliberately truncated reasoning traces, enabling fine-grained thinking budget control at inference time
-
All the work is done on a 12B model, only at the end, it is pruned by Minitron
- Finally, both the base model and aligned model were compressed so as to enable inference over context lengths of 128k tokens on a single NVIDIA A10G GPU (22 GiB of memory, bfloat16 precision). This was done by extending a compression strategy based on Minitron (Muralidharan et al., 2024; Sreenivas et al., 2024; Taghibakhshi et al., 2025) to compress reasoning models subject to constraints.
-
Nemotron-CC-Math-v1: 133B-token math dataset from Common Crawl using Lynx + LLM pipeline (Mahabadi et al., 2025). Preserves equations, standardizes to LaTeX, outperforms previous math datasets on benchmarks
Architecture
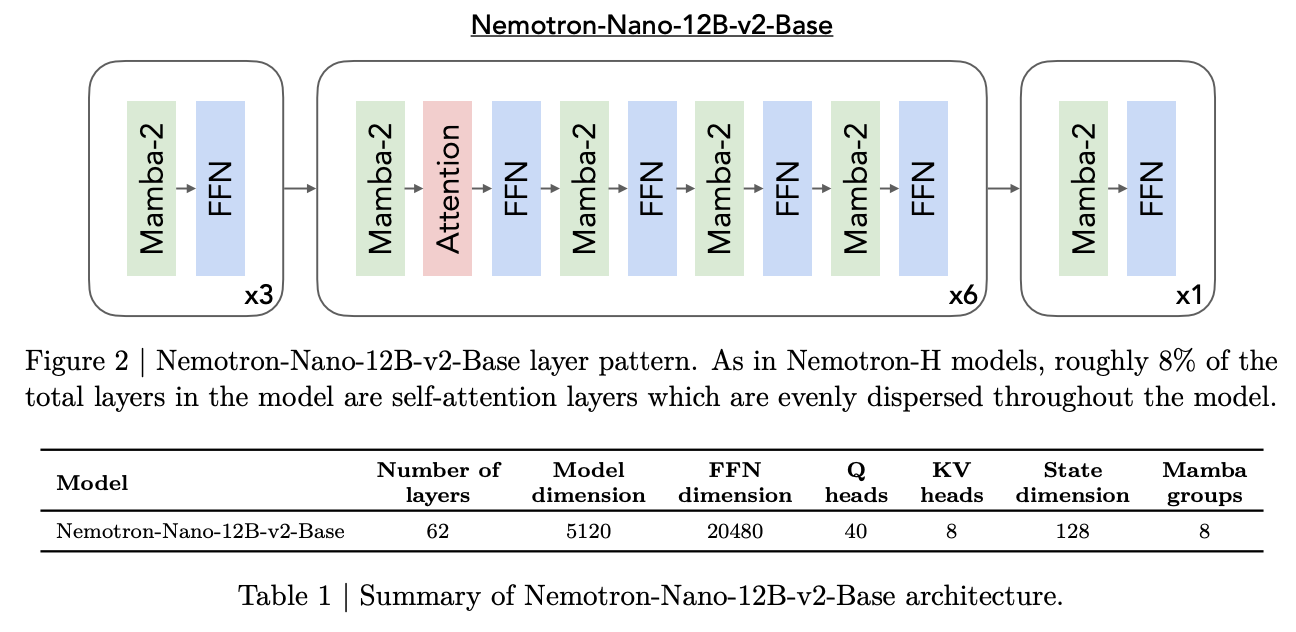
- Notable points
- squared ReLU for FFN
- no position embeddings everywhere (NoPE)